Menu
Tools
Frameworks UnInvisible Signal Builder AI Visibility Glossary AI Brief The Builder’s LogAEO Industry Guides
All guides SEO & AEO for Home Remodelers SEO & AEO for HVAC Companies SEO & AEO for Plumbers SEO & AEO for Painting Contractors SEO & AEO for Real Estate Agents SEO & AEO for Tax Professionals SEO & AEO for Marketing Agencies SEO & AEO for Independent MusiciansAI Foundations
Start here: The Hub The Mental Model Build a Canonical Bio When the Fetch Tool Fails 3 LLM Behaviors Legibility, Eligibility, Extractability Work With MeThe LEE Model: 3 AI Visibility Conditions That Make Content Recommendable
Legibility, Eligibility, and Extractability are the three conditions your content needs before AI systems are likely to recommend you. Here’s what each one means, and how to tell which one you’re missing.
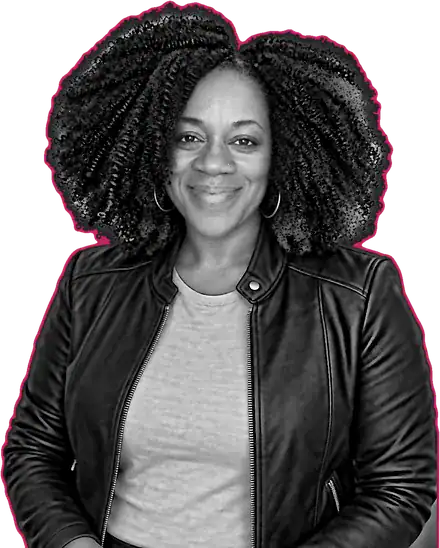
Legibility, Eligibility, and Extractability are the three conditions content has to meet before AI systems are likely to recommend it. They work as interdependent conditions, not interchangeable priorities. This is the LEE Model for AI recommendability.
This piece comes out of the mental model on LLM behavior optimization. Read the mental model →
Here’s what I keep seeing when I do visibility audits for founder-led companies. The content is solid. The company has genuine expertise, processes that deliver results, and wins under its belt, whether that’s been documented or not. But when I ask an AI system to describe them, it either hedges, gets a big thing wrong, lines them up in a row of can’t-tell-them-apart competitors, or surfaces someone else entirely.
And when I dig in, the problem is almost never the thing they asked me to fix (usually recommendations). They’ve done all the right things. But they’ve usually been optimizing for one aspect of machine visibility, not all three. Something inevitably stays under-built.
This is one of those concepts that sat outside my conscious mind for a while. Like the answer that sits on the tip of your tongue but doesn’t get clear enough to say out loud. It cycled in my mind for weeks before I stumbled onto a mental model that made sense of what I’m seeing, both as a consultant and in the wider market.
And it’s this: AI visibility isn’t one problem. It’s three problems, interdependent, where each one has to be solved to keep the others from degrading.
Legibility is non-negotiable. Without it, the other two won’t work. But all three are mutually reinforcing. And once you see it, you can’t un-see it. (If you want the origin story, here’s the session where it landed.)
If you’d asked me about this a few days after I first published it, I would’ve said there are three tiers: Legibility, Eligibility, and Recommendability. And I would’ve described them as sequential gates, not interdependent conditions.
But recommendability got stuck in my craw because I couldn’t resolve it neatly. Recommendable like how? To whom? Which parts? Being “recommendable” is more abstract than definite. And answers in LLMs are heavily shaped by what the machine knows about the user, so recommendability gets pretty subjective.
I knew there was another door to push through beyond Legibility and Eligibility. A day after I originally published this, extractability emerged as the better model. Extractability is the condition that makes recommendability possible. And that’s what I think is most valuable here: understanding the conditions needed to position LLMs as sales channels.
What I originally wrote: “AI visibility isn’t one problem. It’s three problems, stacked in sequence, where each one has to be solved before the next one can be addressed.”
Why each condition is non-negotiable
Legibility, Eligibility, and Extractability are the conditions you create for machines to understand your entity, trust your capabilities, and safely extract your content. Clearing one doesn’t automatically clear the next. And optimizing for extractability before the other two are in place tends to waste resources and produce inconsistent results.
Here’s what happens at each failure point:
Three problems. Three fixes. The diagnostic is figuring out which one you’re actually dealing with before doing any more work.
Condition 1: What is legibility in AI visibility strategy?
Can the machine identify you accurately without visiting your website?
Legibility is the degree to which an AI system can identify, parse, and connect the information that makes up a person or business as one coherent entity. A legible entity is one the machine can describe accurately, consistently, and without guessing.
This is the first brick. It’s the layer I spend the most time on with clients, and the one that’s most often missing entirely. You can see what that looks like in this active disambiguation engagement.
A legible entity is one the machine can describe without guessing. It knows your name, the same name, across every surface where you appear. It knows your role, what you do, who you serve, and what makes you distinct. And it can build that picture from everything published about you and by you, not just your own website.
The failure usually isn’t that someone hasn’t done the work. It’s that the work was never structured in a way machines can read. A founder who’s published under three name variations, or whose LinkedIn and website tell different stories, or whose content is credited to “the team” instead of a named person: that’s an illegible entity. Not because the expertise isn’t real. Because the machine can’t assemble the pieces.
What legibility requires
- A canonical bio: two to three consistent sentences, appearing identically across every published piece and profile. It’s the machine’s main anchor for connecting content to a named person. Here’s the full guide.
- : Article, Person, and Organization schema. The structured layer that tells machines what this content is and who wrote it.
- Cross-platform consistency: same name, same title, same specialization, everywhere your name appears. Inconsistency is the most common legibility failure and the easiest to fix.
- An entity identity page that introduces the person, not just the services. A services page tells the machine what you offer. An About page tells it who you are. Only one of those builds legibility.
This is the layer the Minimum Viable Knowledge Graph is built to address. It maps the five nodes of your entity structure (identity, specialization, audience, expertise, and proof) and shows where the architecture is thin before any content strategy work begins.
Failure mode: the work leaks instead of compounding. You build for eligibility and extractability (content, press, optimized pages), and the machine credits it to a fragmented version of you that doesn’t match current reality. Or to someone with a similar name and stronger entity signals.
Condition 2: What is eligibility in AI visibility strategy?
Does the machine consider you credible enough to include in an answer?
Eligibility is the degree to which an AI system judges an entity credible, authoritative, and trustworthy on a given topic. An eligible entity hasn’t just been identified. It has earned a place in the answer set for a specific question.
Legibility tells the machine who you are. Eligibility tells it whether you belong in the answer. Those are genuinely different questions with genuinely different answers.
What you say about yourself is a claim. What others say about you is evidence.
The machine weighs them differently. It checks whether your self-description is confirmed anywhere else. If the only place your expertise appears is your own website, that’s a single-source dependency. And single-source dependencies produce hedging.
This is where lives, but not as a checklist. It’s the machine’s overall reading of everything it can find about you, weighted toward what credible outside sources have already confirmed.
What eligibility requires
- Corroboration: third-party sources confirming what you claim. Press mentions, guest articles on credible publications, podcast appearances, citations in industry reports.
- Documented outcomes: specific case studies with client type, intervention, measurable result, and timeline. Generality is invisible to machines. Specificity is what makes a case study citable.
- Track record: consistent, dated content on the same topics over time. One article is a claim. Twelve articles over eighteen months is a pattern the machine reads as expertise.
- First-hand evidence: specific scenarios in your content that could only come from someone who’s done the work. A specific story tied to a named outcome reads as proof of direct experience.
Traditional authority signals (VC funding, research budgets, mainstream press) are structurally out of reach for a lot of the founders I work with. That’s not a personal deficit. It’s a structural gap in how authority has historically been assigned and documented.
For these clients, compensating signals aren’t a workaround. They’re the strategy: Notion Marketplace listings, Amazon author pages, local press, industry association citations, podcast networks, community platforms. They do real work in the machine’s eligibility calculus when they’re built deliberately and consistently. The Compensating Signals framework has the full breakdown.
Failure mode: hedging replaces recommendation. The machine knows who you are but hedges: according to their website, she claims, the company states. Hedged claims rarely get recommended. They get footnoted. And that hedging language is diagnostic data, not noise. More on that below.
Condition 3: What is extractability in AI visibility strategy?
When the machine is building an answer, can it use you?
Extractability is the degree to which an AI system that could include an entity in a generated answer is actually able to safely pull usable content from that entity’s work (website, LinkedIn, Substack, Medium, and so on). An extractable entity’s content is structured, specific, and citable enough for the machine to answer a precise question with it, and to attribute it with confidence instead of hedging.
The Thunderstruck example
I stumbled onto a great example of this recently (I talked about it in this LinkedIn post). In my downtime, I started wondering about the release date of AC/DC’s “Thunderstruck.” Did a little digging and pulled up Google’s for the song.
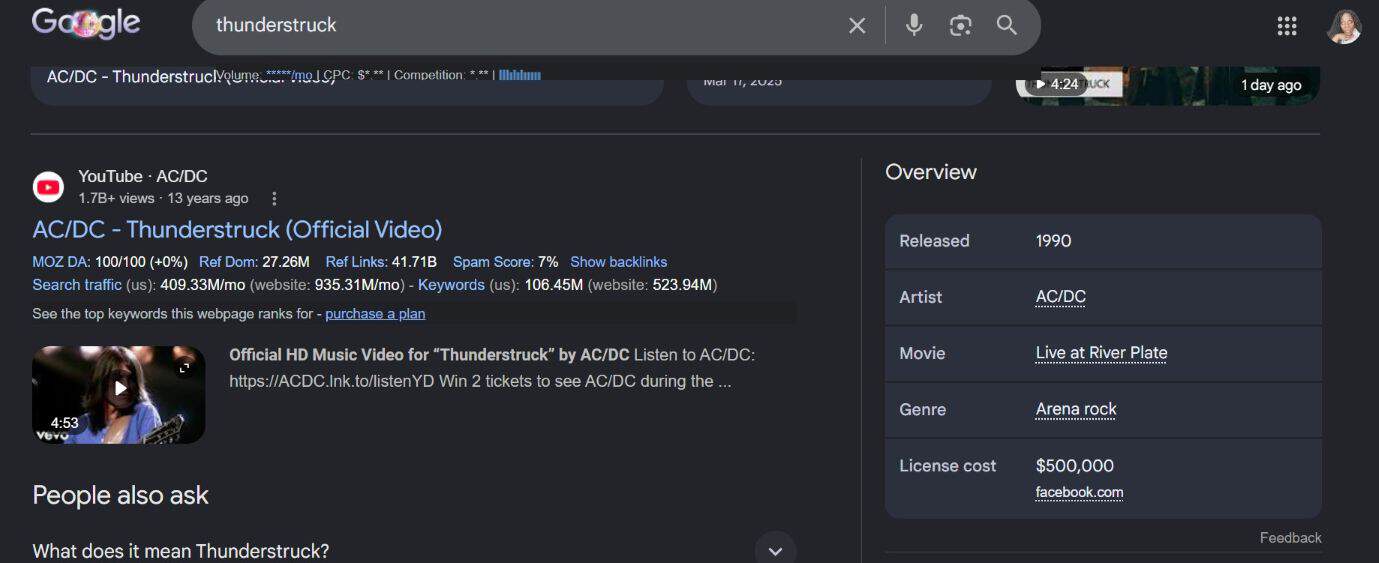
After looking up a few other big songs, I noticed that licensing cost wasn’t a typical knowledge panel field, which suggested it was coming from a knowledge graph node rather than a standard panel feature. So I clicked the Facebook link listed in the panel and found the stat in a 2022 Facebook post that got almost no engagement.
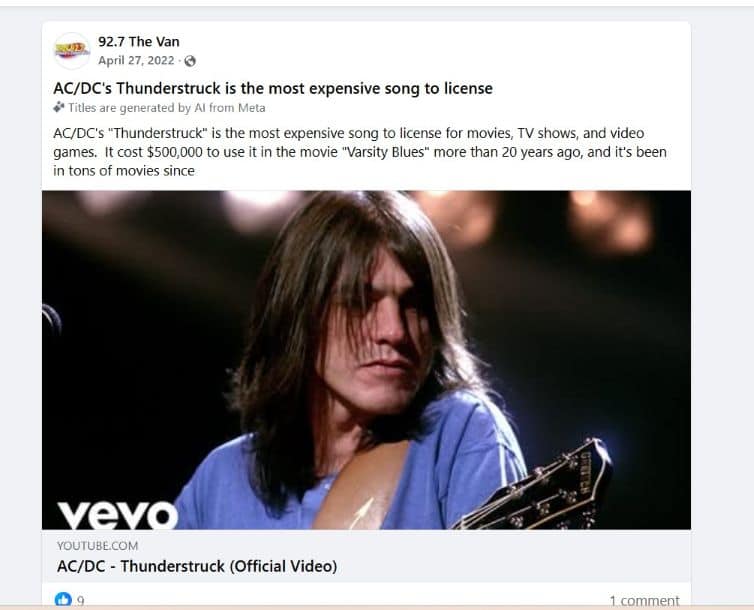
The stat itself circulated in music industry publications back in 2014, eight years before this Facebook post went up. So why would Google link to a Facebook post that wasn’t the original source, instead of one of the older, high-authority articles?
My take: extractability. The Facebook post was clean, clear, and delivered everything you needed in 39 words. The original music-site article had the facts scattered across a page with a video loading, ads, and not enough of the good stuff above the fold.
Eligibility earns you a seat at the table. Extractability moves you forward as a candidate for recommendation.
This is the layer that gets skipped. Not because people don’t care about it, but because they don’t know it exists as a separate problem. The assumption is that if you’re visible and credible, you’ll be recommended. That’s not necessarily how it works. Extractability is about the content architecture of trusted entities: whether your content is built in forms AI systems can lift, use, and attribute without modification.
A machine building an answer needs something usable. A definition it can quote. A process it can cite. An answer it can surface for a specific question. Content that’s well written and well argued but not built for extraction gets passed over. Not because the machine doesn’t know you or trust you, but because it can’t use what you built.
What extractability looks like
- Definitional snippets: named concepts defined in two clean sentences (what it is, why it matters). This is the format AI systems tend to pull for direct-answer queries, and it makes you the canonical source for that definition.
- Answer-first structure: lead with the answer, then support it. Content that buries the answer in paragraph four tends to get passed over for content that leads with it. That’s not a style preference; it’s closer to how retrieval systems are built to work.
- Named proprietary frameworks: a named concept with a consistent definition across all your content makes you the definitional source. The LEE Model is one. The Minimum Viable Knowledge Graph is another. Without the name, the idea floats unattributed.
- Process architecture: numbered step-by-step sequences, one sentence per step. These surface often for how-to and voice queries.
- Recency signals: dated content that confirms the information is current. AI systems ask is this still true?, not was this ever true? Update dates and refresh statistics when content is meaningfully revised.
Failure mode: the branded search trap. Strong performance on searches for your name. Thin or missing performance on , the questions your ideal client asks before they know you exist. The machine knows you. It trusts you. But when it builds an answer to a question your brand should own, it reaches for someone whose content it can actually extract and use.
How to diagnose which condition is missing
Before building strategy, find the gap. Building for the wrong condition wastes resources and produces results that feel random.
There’s a faster way to run this diagnostic than guessing: watch the language AI systems use when they respond to questions about you. Hedge language (she claims, according to their website, appears to specialize in, you should evaluate whether, limited track record) is the machine’s confidence score made visible. It’s not random phrasing. Each phrase points to a specific gap, which points to a specific condition.
| When the machine says… | It means… | Address this condition |
|---|---|---|
| “Some sources describe…” “It’s unclear whether…” “Different versions exist…” | It found you but can’t reconcile the signals into one coherent picture. | Legibility |
| “According to their website…” “They claim…” “You should evaluate whether…” | It identified you but can’t corroborate what you’re claiming. | Eligibility |
| An accurate description, but you’re invisible for unbranded category questions | It trusts you but can’t use your content to answer the questions it’s getting. | Extractability |
Three questions to confirm your bottleneck
If not (or it’s hedged, outdated, or mixing you up with someone else), start here: canonical bio, schema, an About page that introduces the person, cross-platform alignment.
“She claims” and “according to their website” mean it found you but can’t confirm you. Build corroboration: guest articles, press, podcasts, documented client outcomes.
Branded dominance with thin category presence is the extractability signature. Add definitional snippets, name your concepts, lead sections with the answer.
Legibility comes first, but the diagnostic doesn’t have to. Run the hedge signal check first. It usually tells you exactly where to look before you’ve asked a single strategic question.
Where the LEE Model fits in your AI visibility strategy
LEE is the destination map for the AI Foundations series. The other pieces explain how machines work and what breaks when things go wrong. This piece tells you where you’re trying to land. Read them in order:
- 01 · START HEREBuild a Canonical BioThe first brick of legibility.
- 02 · GROUND LEVELWhat to Do When the Fetch Tool FailsThe three retrieval failures: what breaks and why.
- 03 · TERRAIN MAPThe 3 LLM BehaviorsRecall, retrieval, inference: how machines actually work.
- 04 · DESTINATION MAP · YOU ARE HEREThe LEE ModelLegibility, Eligibility, Extractability: where you’re trying to land.
Frequently asked questions
What is the LEE Model?
The LEE Model is Sorilbran Stone’s framework for AI visibility. It names three interdependent conditions content has to meet before AI systems are likely to recommend it: Legibility (the machine can identify you), Eligibility (it trusts you enough to include you), and Extractability (it can safely pull usable content from your work).
What is legibility in AI visibility?
Legibility is the degree to which an AI system can identify, parse, and connect the information that makes up a person or business as one coherent entity. A legible entity is one the machine can describe accurately, consistently, and without guessing.
What is eligibility in AI visibility?
Eligibility is the degree to which an AI system judges an entity credible, authoritative, and trustworthy on a topic. It’s built mainly through corroboration: third-party sources confirming what you claim about yourself.
What is extractability in AI visibility?
Extractability is whether an AI system can safely pull usable content from your work when it builds an answer. Definitional snippets, answer-first structure, named frameworks, numbered processes, and clear dates all make content more extractable.
Why did recommendability become extractability?
Recommendability is a machine behavior. It’s shaped by the user’s context and isn’t something a brand can directly control. Extractability is the condition that makes recommendation possible, and it’s buildable, repeatable, and auditable, so it belongs in the model.
How do I know which LEE condition I’m missing?
Watch how AI systems describe you. Identity hedges (“some sources describe”) point to legibility. Credibility hedges (“according to their website”) point to eligibility. An accurate description with no presence on unbranded category questions points to extractability.
Visibility Engineer and founder of Five-Talent Strategy House in Detroit. She helps founders and marketing teams build the infrastructure that gets them found, and accurately represented, in AI-generated answers.
We’ll read how AI systems describe you and show you whether it’s legibility, eligibility, or extractability, before you build anything else.
Schedule a Strategy Call